Phase 1 improvement: +0.189 percentage points, 95% CI [0.044, 0.333]; Holm p = 0.0412. Comparison scope →
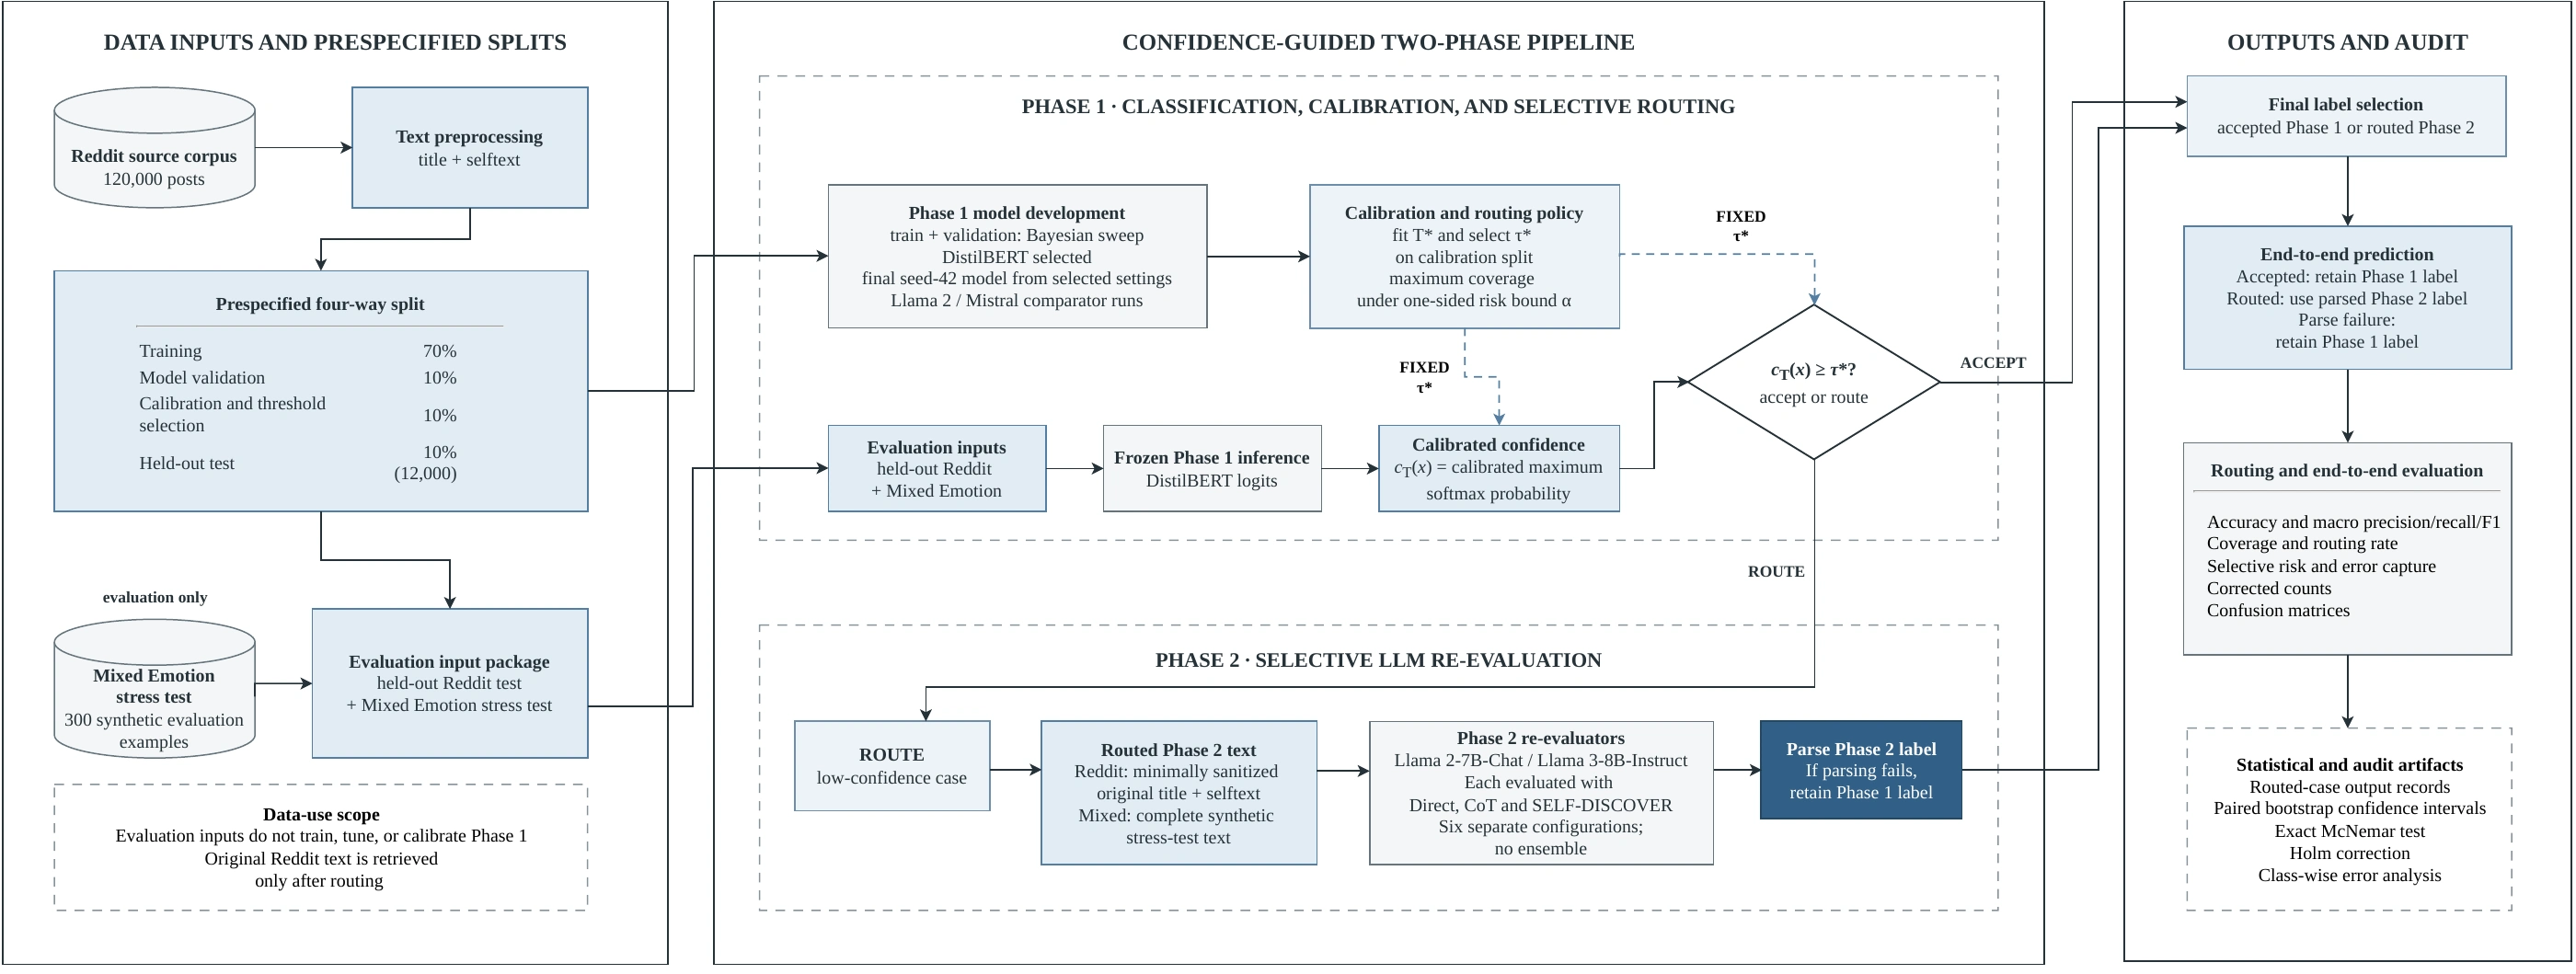
Select → calibrate → re-evaluate → audit. Three classifier configurations are compared before DistilBERT supplies the fixed routing policy. Accepted predictions stay unchanged; routed posts receive a fresh LLM decision. Full-size architecture ↗
RESEARCH CONTRIBUTIONS
What this study adds
A linked evaluation of the classifier, the router, and the re-evaluator, with a fixed-protocol follow-up on 9,000 separate posts.
01 Classifier-to-LLM pipeline
Connect three-model classifier selection to selective original-text re-evaluation in one auditable experiment.
02 Calibration-defined routing
Fit temperature and select a threshold on calibration data, then freeze both for evaluation.
03 Corrections and new errors
Audit error capture separately from net corrections, comparing two LLMs and three protocols on matched routed inputs.
04 Task-adapted SELF-DISCOVER
Combine emotion-oriented modules, a reusable model-generated plan, and researcher-authored evidence checks.
The main Reddit and Mixed Emotion evaluations informed prompt development and are exploratory. The separate 9,000-post evaluation used a fixed protocol on the same source. Labels are research proxies, not clinical diagnoses.
Abstract
Large language models can reconsider uncertain classifications, but re-evaluating every input increases generation workload and can introduce new errors. We study confidence-guided selective re-evaluation for three-class emotion classification in social media. A temperature-scaled DistilBERT classifier retains high-confidence predictions and routes the remaining posts to Llama 2 or Llama 3 using Direct, chain-of-thought (CoT), or task-adapted SELF-DISCOVER prompts.
On the exploratory 12,000-post Reddit evaluation, Llama 3 SELF-DISCOVER improves accuracy from 96.92% to 97.20% while re-evaluating 1.82% of posts. On a separate, fixed-protocol evaluation of 9,000 posts, it produces 17 net corrections while routing 1.23%, with a significant improvement over Phase 1 under the specified Holm adjustment. SELF-DISCOVER has the highest observed accuracy across the evaluated sets, but its differences from Direct and CoT are not statistically resolved on Reddit. The results describe a proxy-label classification task, not clinical diagnosis.
01 / METHOD
Confidence first, re-evaluation when needed
Phase 1: compare three classifiers, select DistilBERT
Before LLM re-evaluation, we compare three classifier configurations on the same 12,000-post Reddit test set, using seeds 42, 43, and 44 and a four-trial search budget per model. DistilBERT has the highest observed mean accuracy and the fastest measured inference under this protocol.
Phase 1 classifier comparison · three-seed means
Classifier
Adaptation
Accuracy ± SD
Macro F1 ± SD
Posts/s
DistilBERT (selected)
Full fine-tuning
96.88 ± 0.04%
96.88 ± 0.04%
4,959.5
Mistral 7B
Frozen backbone + linear head
95.36 ± 0.08%
95.36 ± 0.08%
51.7
Llama 2 7B
Frozen backbone + linear head
95.17 ± 0.07%
95.17 ± 0.07%
55.5
Source: manuscript Table 2. Throughput: NVIDIA A100-SXM4-40GB, fp16, batch 32, 256-token cap; mean of three timing repetitions, separate from training seeds. This compares the tested configurations, not fully fine-tuned 7B models. Bold denotes the highest observed value, not statistical significance.
From model selection to the final pipeline. The downstream experiments retain the selected seed-42 DistilBERT run. Its Reddit accuracy is 96.92%, distinct from the 96.88% three-seed mean above. Compare its predictions before and after re-evaluation →
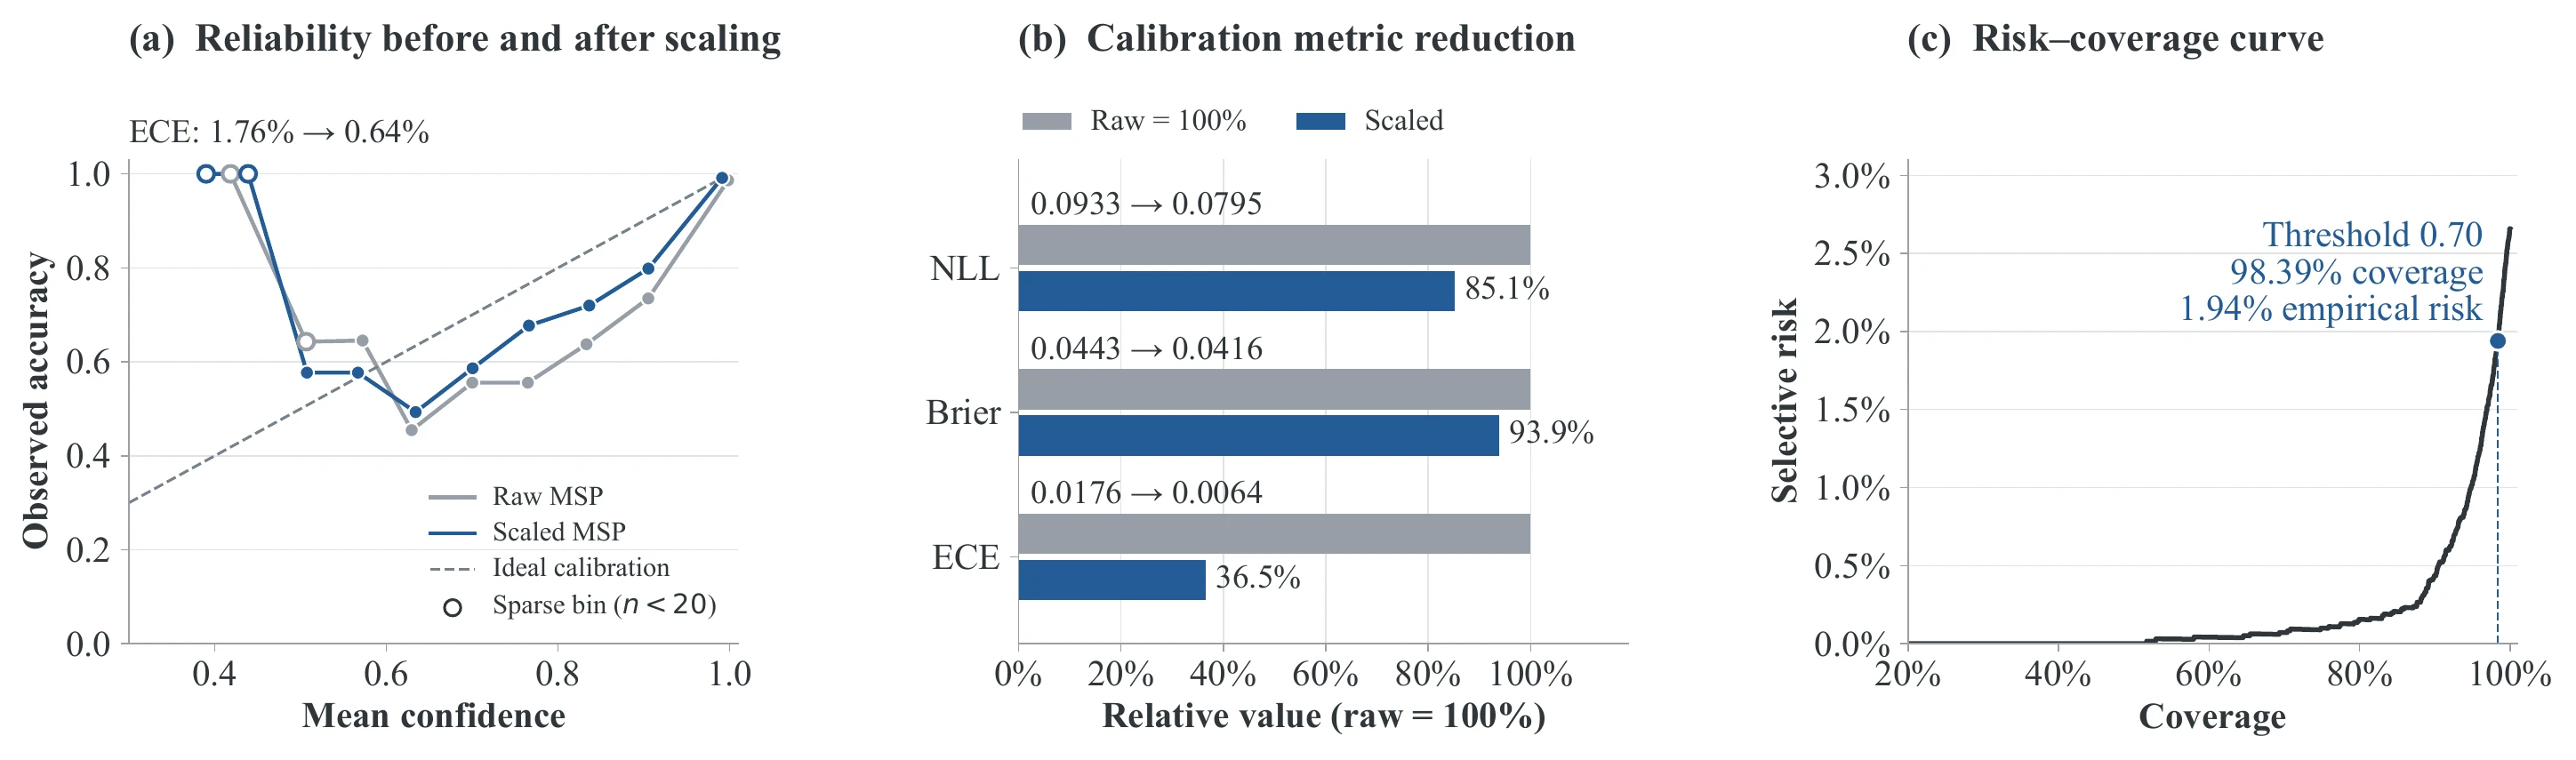
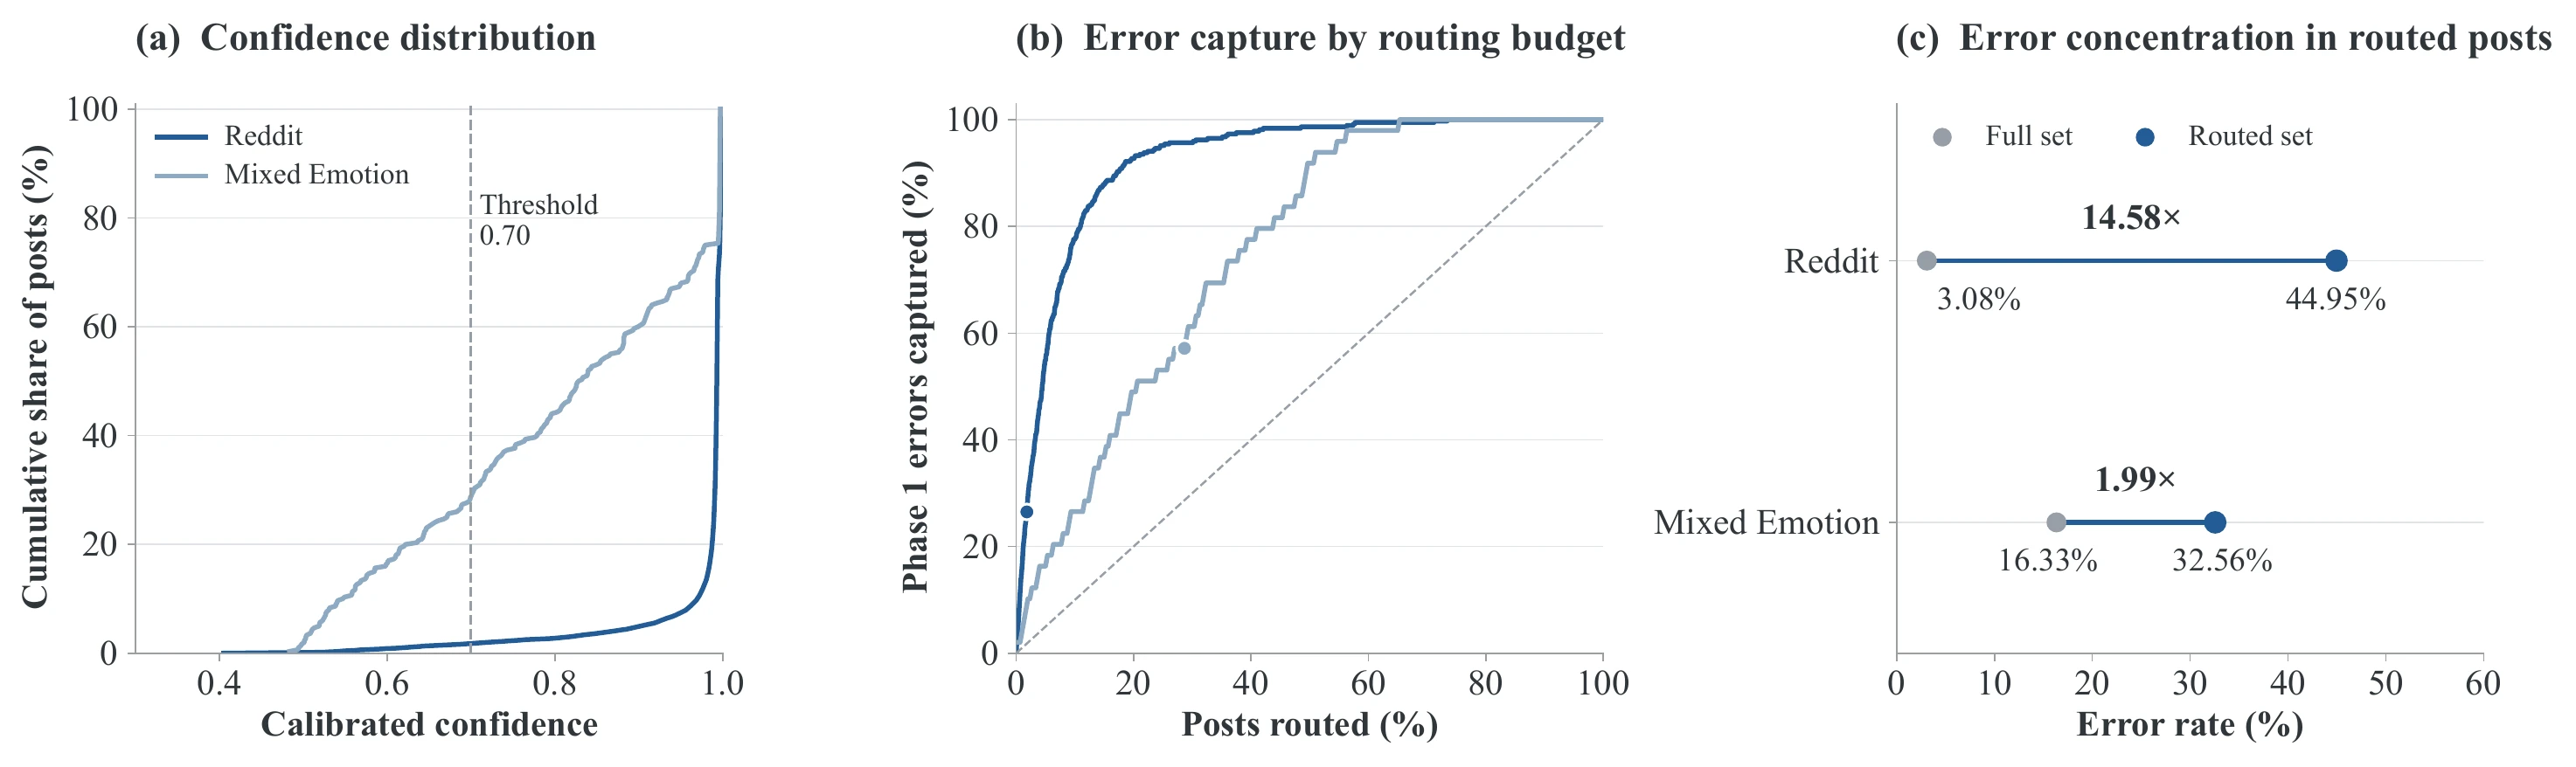
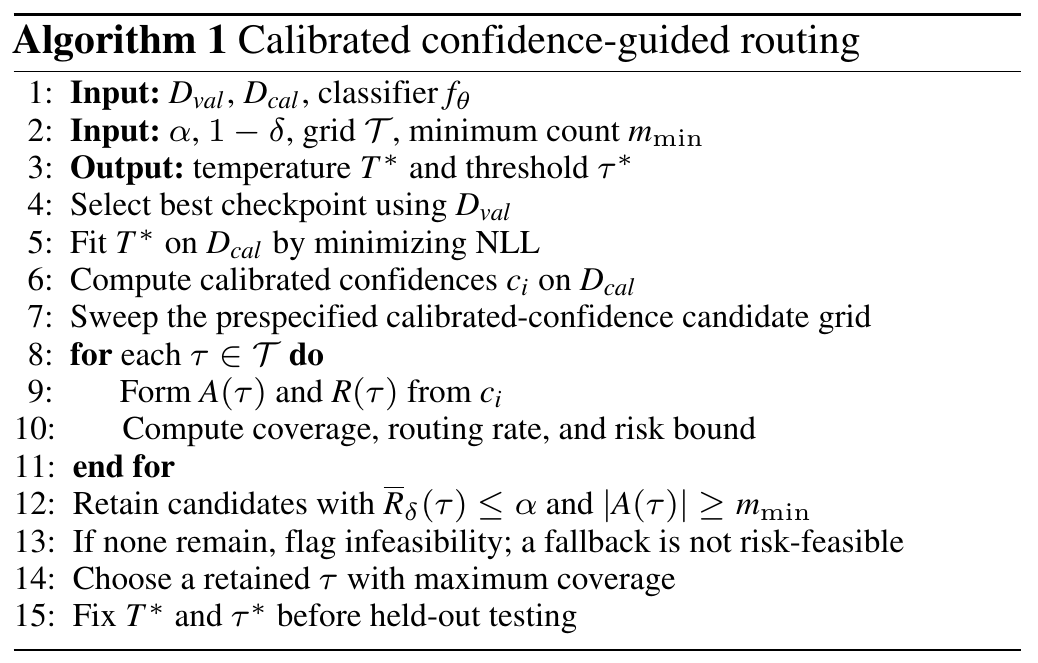
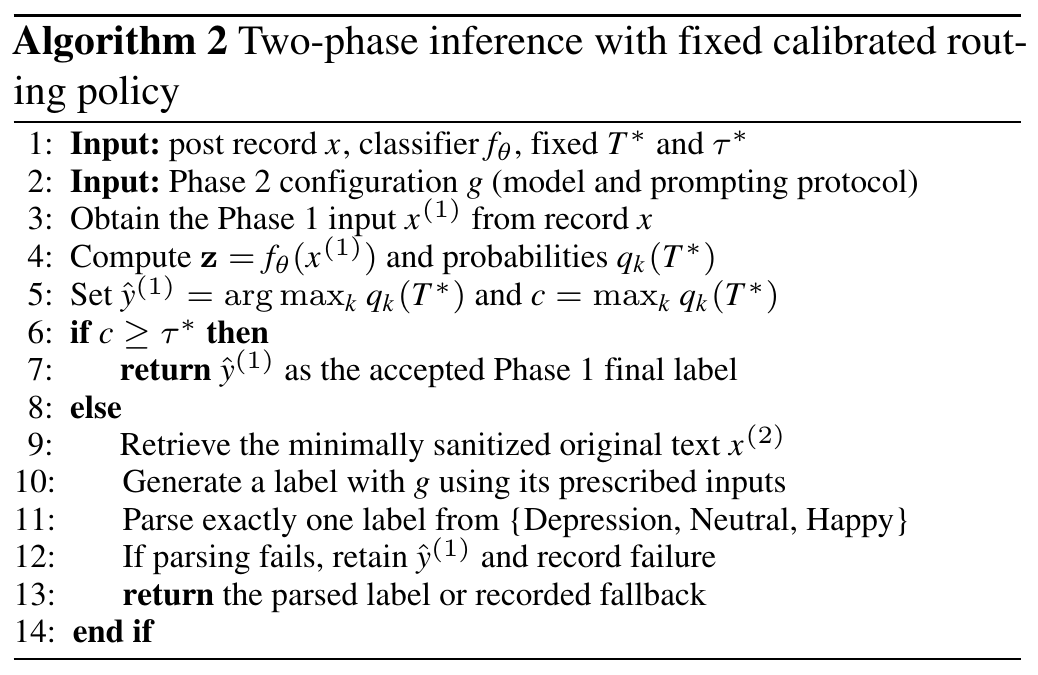
Phase 1 predicts Depression, Neutral, or Happy. Temperature scaling adjusts the model's confidence, and a threshold determines which predictions are retained. The selected threshold is τ = 0.70: 11,807 of 12,000 calibration posts are accepted, with 1.940% empirical error and a 2.162% one-sided Clopper–Pearson upper bound.
The lowest candidate in the prespecified 0.70–1.00 grid already satisfies the 5% risk budget, so the grid boundary determines the operating point. Temperature fitting and threshold selection use the same calibration partition. The pointwise bound is not a simultaneous post-selection guarantee and does not guarantee the same risk under distribution shift.
Calibration diagnostics Reliability, NLL, Brier score, and ECECalibration. Temperature scaling reduces NLL, Brier score, and ECE. The marked operating point retains 98.39% of the calibration set.
Phase 2: re-evaluate only routed posts
Routed posts receive a fresh evaluation by Llama 2 or Llama 3; accepted posts retain their Phase 1 labels. Each protocol uses the same routed inputs within a dataset/model comparison.
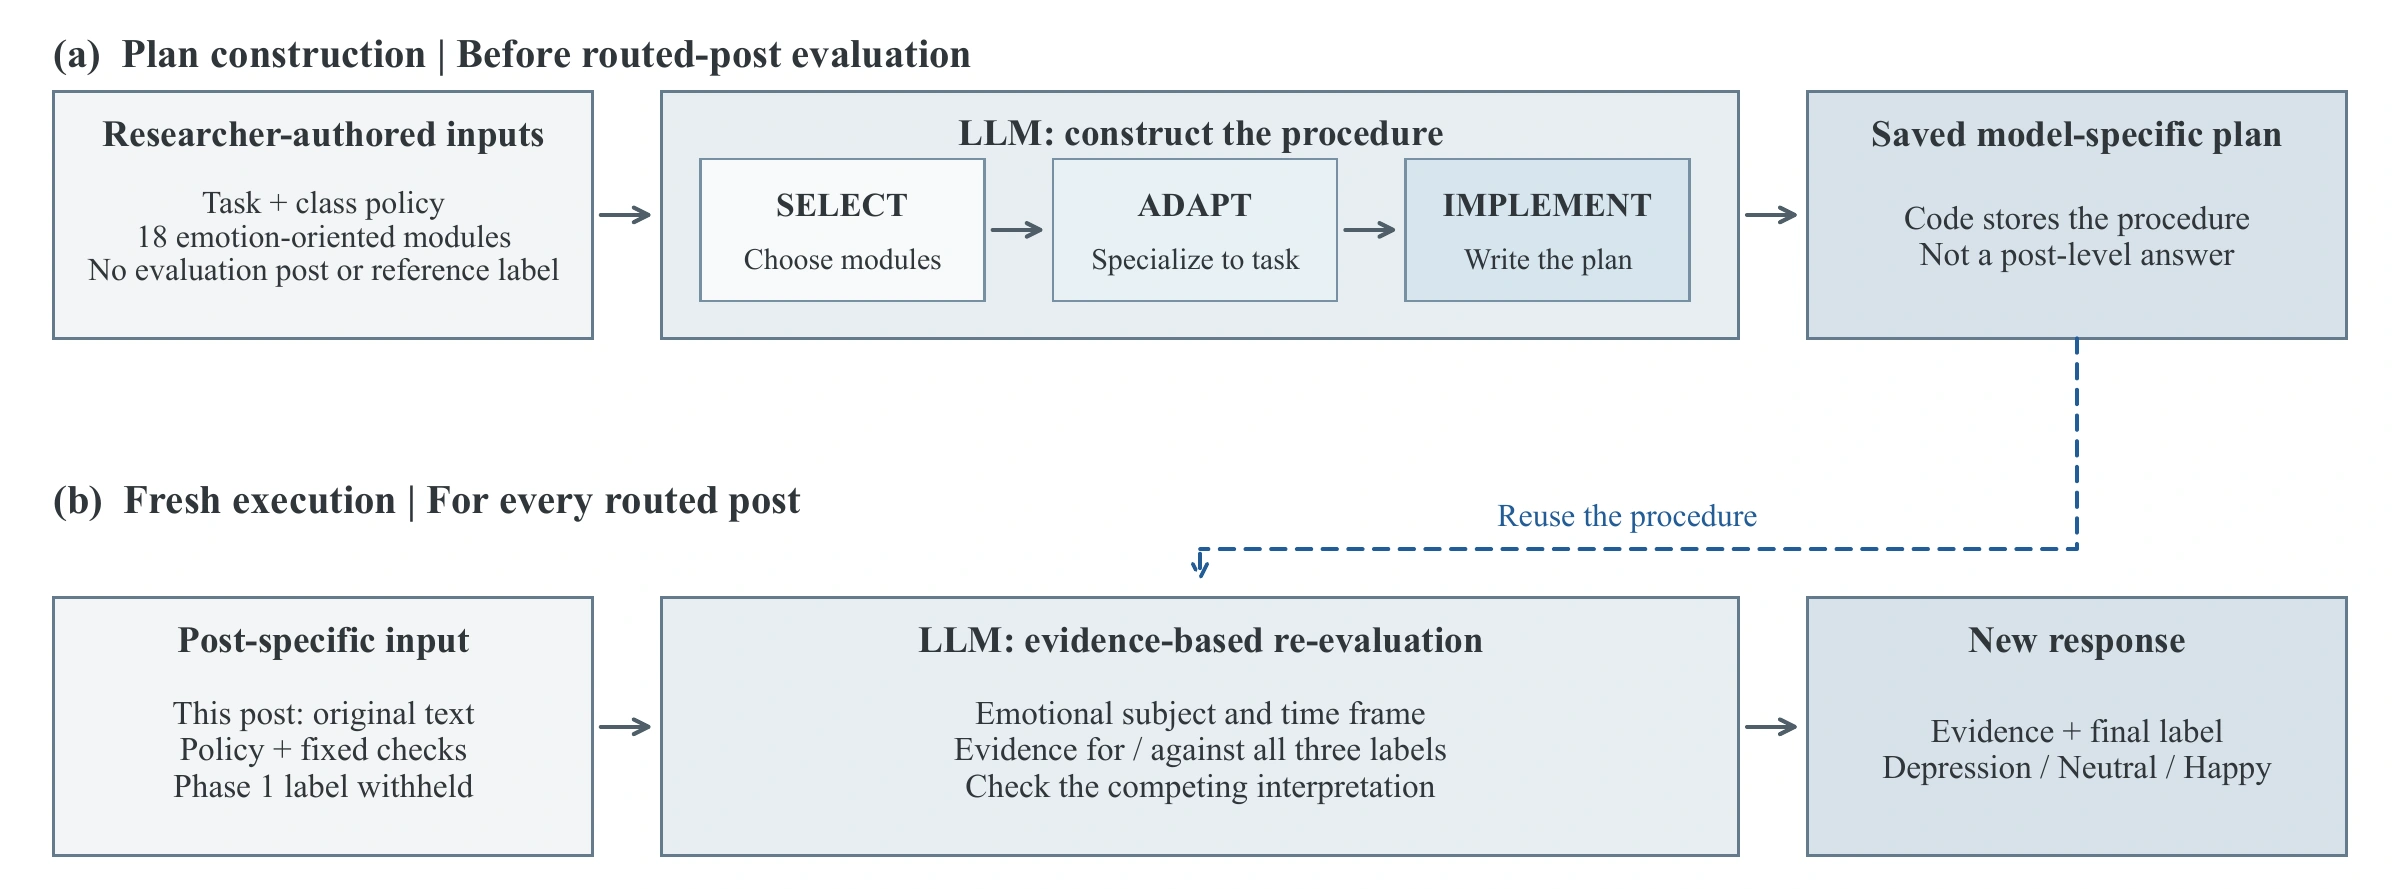
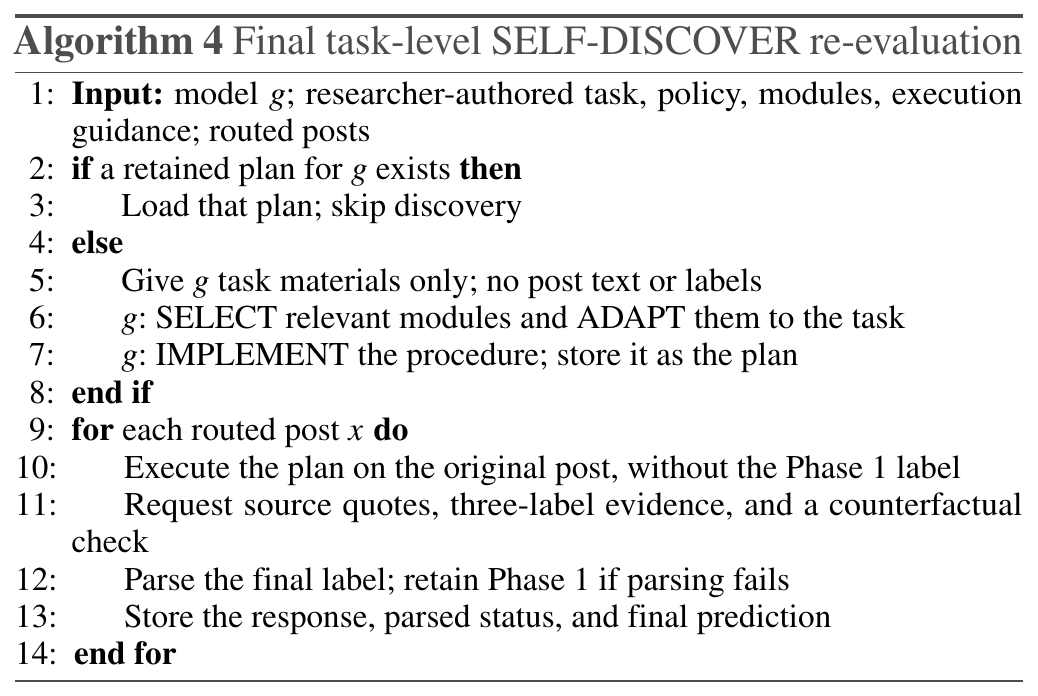
Direct uses one generation call. CoT uses five dialogue turns, including acknowledgment and text-response turns. SELF-DISCOVER constructs a task-level plan from the class policy and 18 researcher-authored reasoning modules, then reuses it for each routed post. Plan construction receives neither evaluation posts nor reference labels.
SELF-DISCOVER adaptation. Each model retains its own unedited plan. Evidence-ledger and counterfactual checks are researcher-authored execution instructions, not discoveries made by the model. See the exact prompts and saved plans.Protocol settings and comparison conditions
Protocol
Calls per routed post
Phase 1 label
Direct
1
Visible
CoT
5
Visible from the comparison turn
SELF-DISCOVER
1, after task-level plan construction
Withheld during reasoning
The protocols differ in label visibility, call structure, and generation budget; the comparison is between complete configurations rather than an isolated test of reasoning components. If the final label cannot be parsed, the Phase 1 prediction is retained.
02 / EVALUATION
From the Phase 1 baseline to final predictions
The additional 9,000-post Reddit run keeps model weights, temperature, threshold, prompts, and the saved plan fixed. It tests the pipeline on separate posts from the same source, not cross-platform generalization. The main Reddit and synthetic Mixed Emotion results are exploratory because both sets informed prompt development.
Compare Phase 1 and final confusion matrices Three evaluation sets
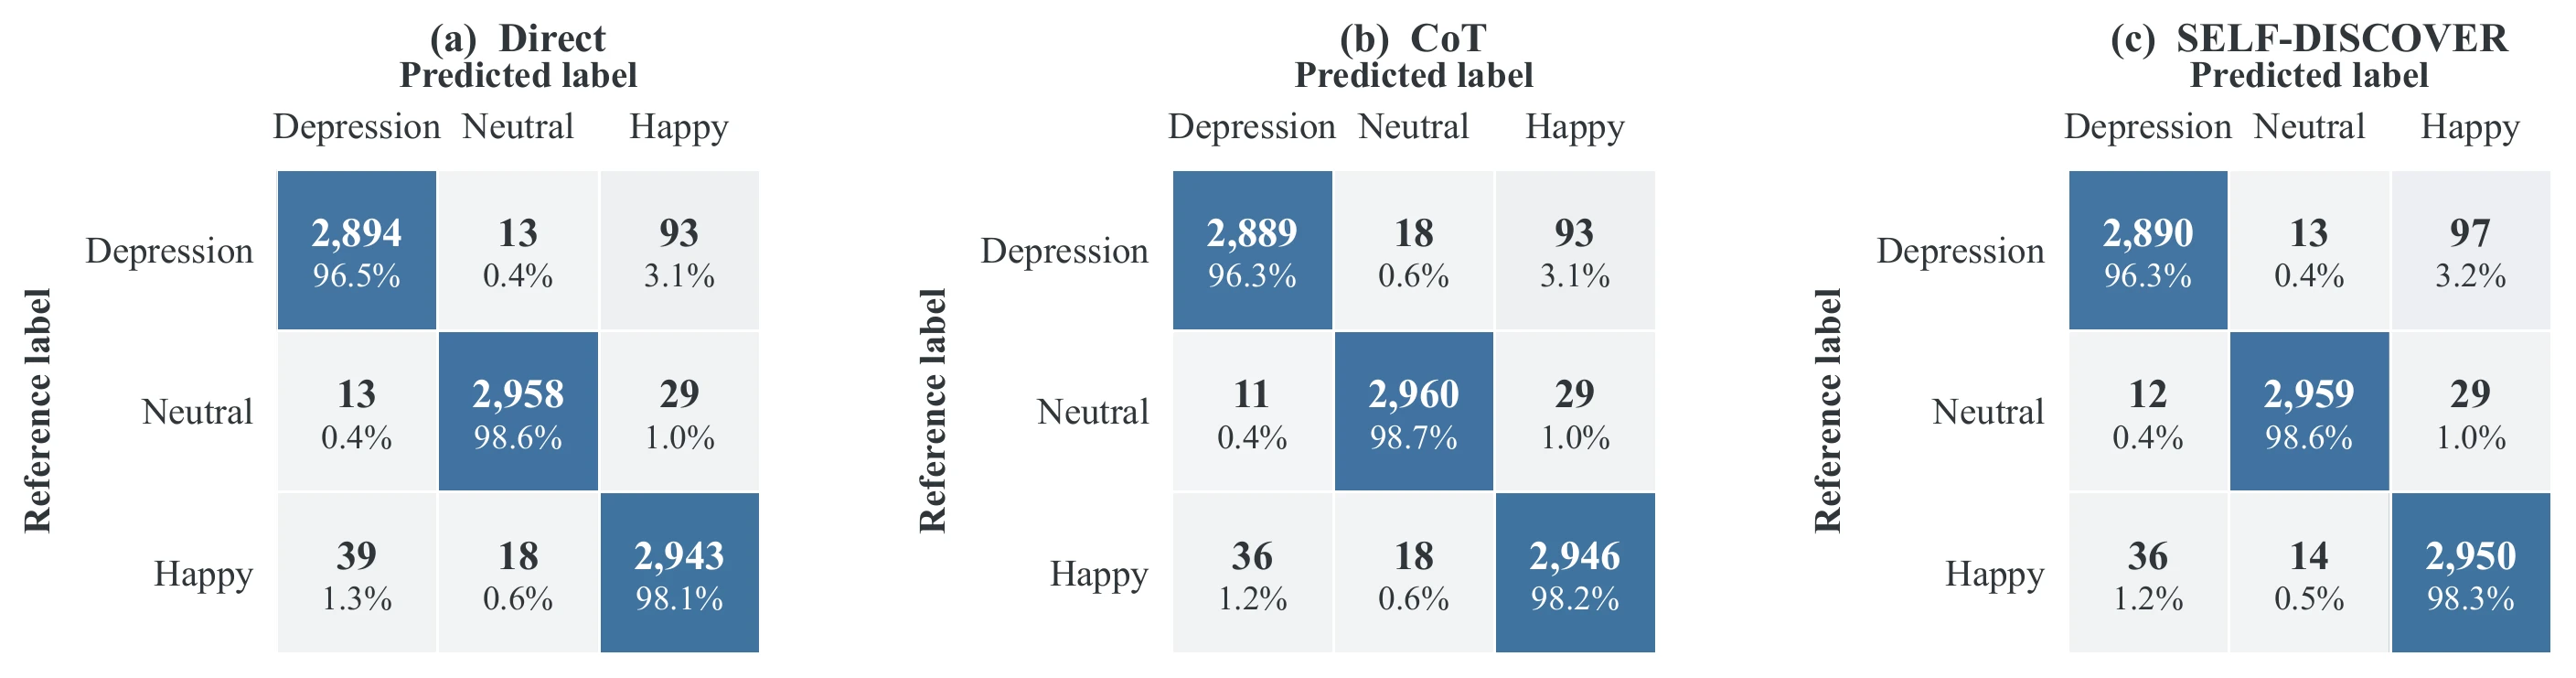
Both matrices use the same reference labels and posts. The baseline is the retained seed-42 DistilBERT run; the final pipeline adds selective Llama 3 SELF-DISCOVER re-evaluation. These are full-set results, not the three-seed model-selection averages.
Rows: reference labels. Columns: predictions. Cells show counts and within-class percentages; both matrices share the same 0–100% color scale. Text-free source predictions.
What changes after re-evaluation?
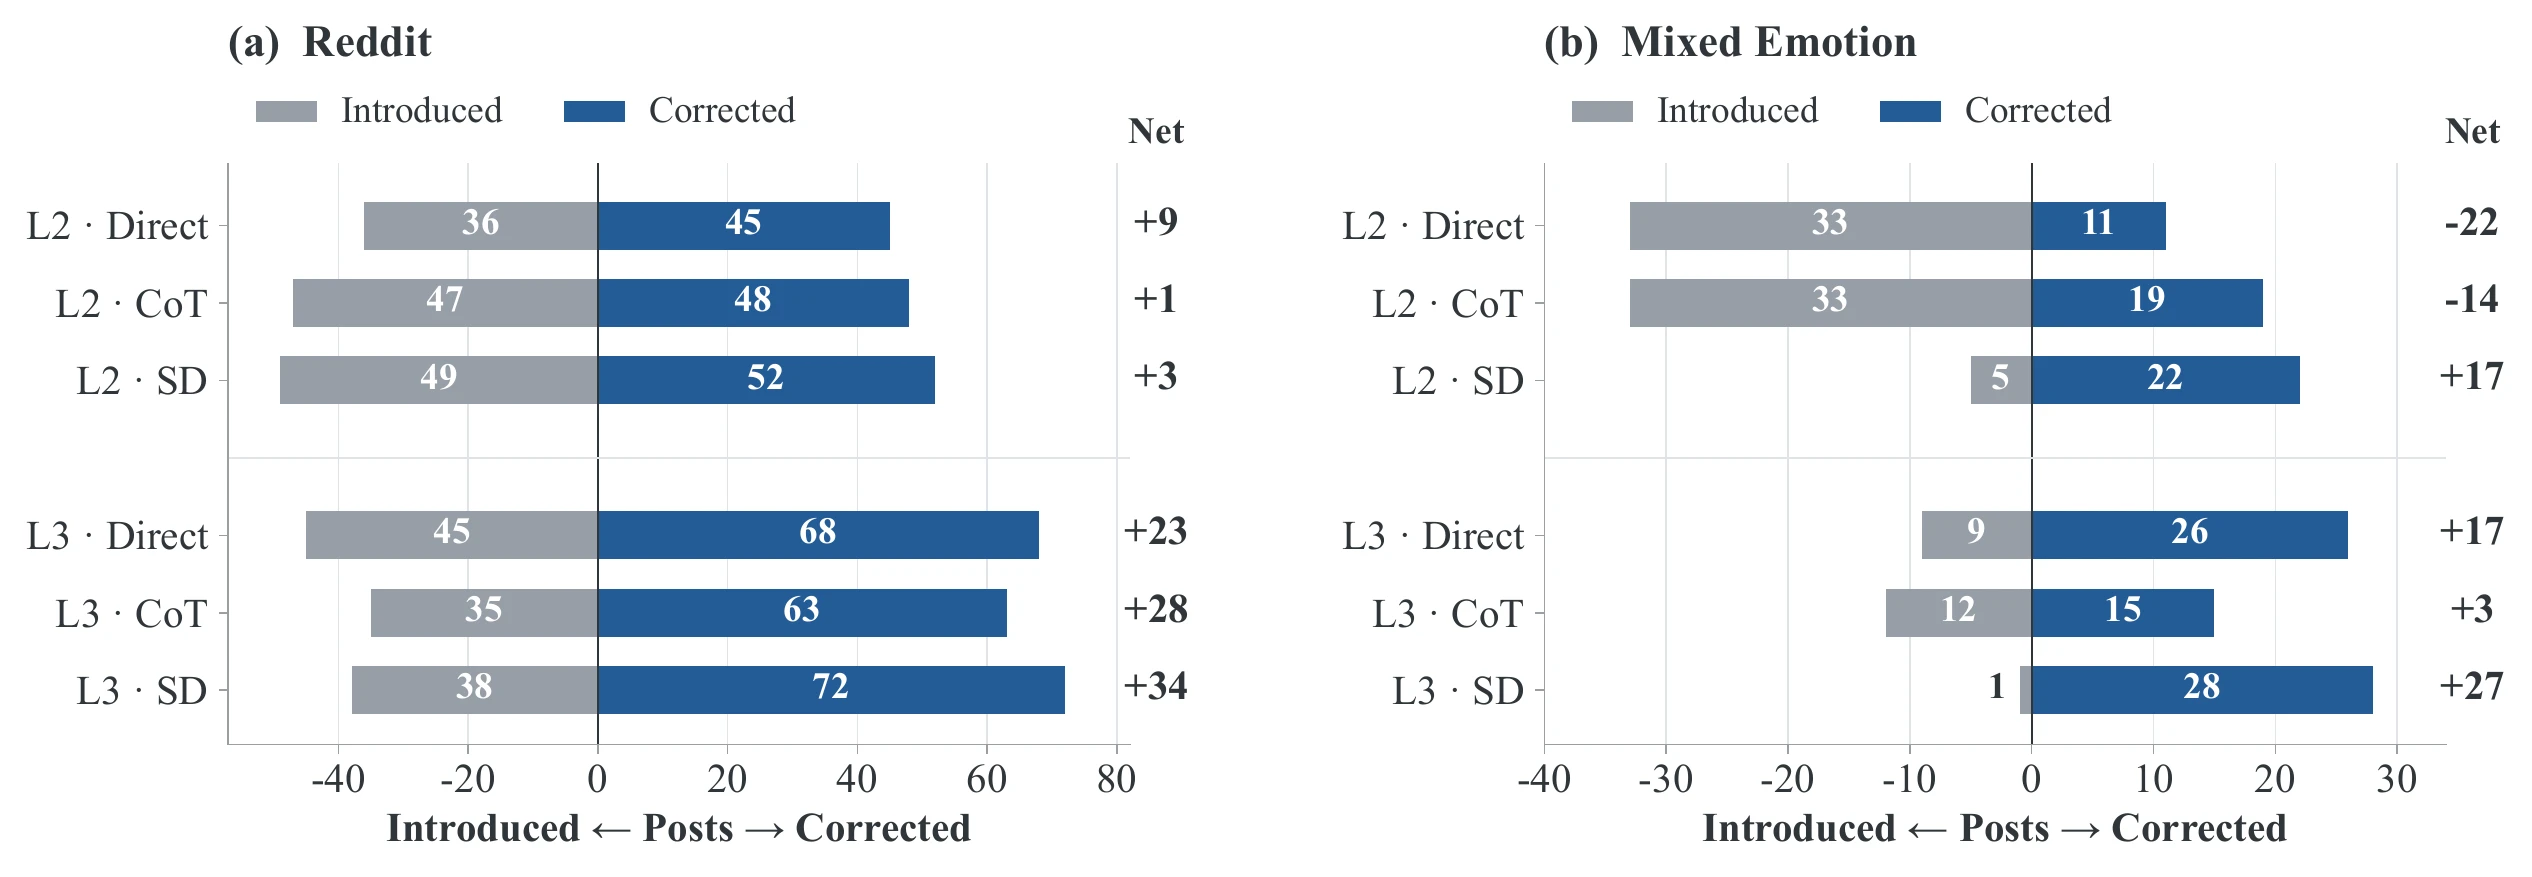
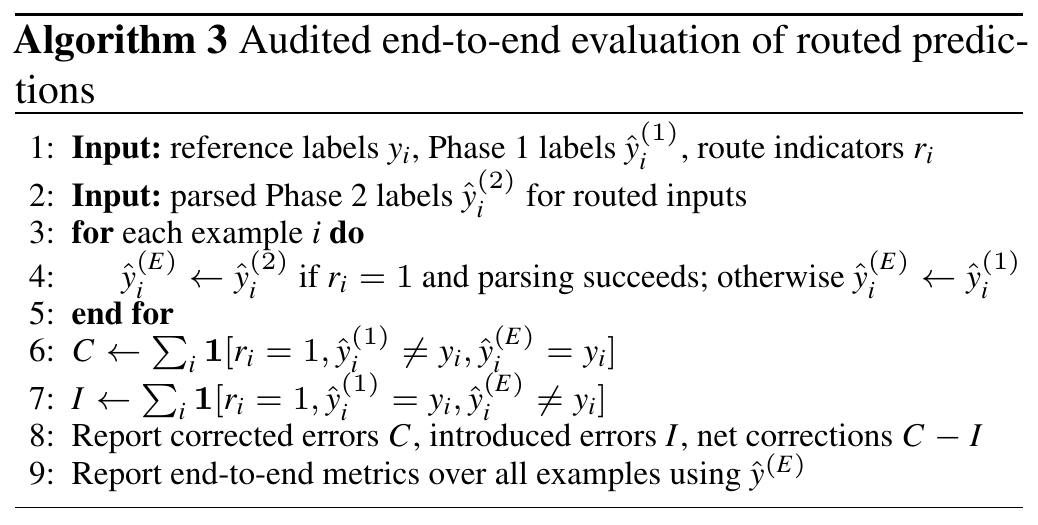
In the fixed 9,000-post evaluation, SELF-DISCOVER corrects 30 errors and introduces 13: 17 net corrections. The other 8,889 posts retain their Phase 1 labels.
Observed counts from the released predictions. Bar lengths use the same scale within each selected comparison.
SELF-DISCOVER across all three evaluation sets Full-set accuracies and correction counts
Llama 3 SELF-DISCOVER compared with Phase 1
Evaluation set
Phase 1
Final accuracy
Routed
Corrected / introduced
Net
Reddit (12,000)
96.92%
97.20%
1.82%
72 / 38
+34
Mixed Emotion (300)
83.67%
92.67%
28.67%
28 / 1
+27
Additional Reddit (9,000)
97.58%
97.77%
1.23%
30 / 13
+17
Correction counts across all six configurationsCorrected and introduced errors. Net correction is the number of Phase 1 errors corrected minus the number of previously correct predictions changed to errors.
Paired statistical comparisons
On the fixed 9,000-post evaluation, SELF-DISCOVER improves accuracy by 0.189 percentage points (95% paired bootstrap CI [0.044, 0.333]). Exact McNemar p = 0.0137; Holm-adjusted p = 0.0412 across the three Phase 1 comparisons. Its four-prediction lead over Direct or CoT is not significant (both Holm-adjusted p = 0.9614 in the separate two-comparison family).
Recorded generation workload
Same 111 routed posts, Llama 3 on NVIDIA L4. Direct produces four fewer net corrections than SELF-DISCOVER at about 2.1% of its recorded generation time.
Additional Reddit evaluation · model-generation regions only
Protocol
Net corrections
Generation time
Direct
+13
54.9 s
CoT
+13
3,116.4 s
SELF-DISCOVER
+17
2,568.5 s
One recorded run. Timings exclude model loading, initialization, I/O, and Phase 1 processing; they are not end-to-end latency or monetary cost.
All 15 evaluated configurations
Full-set results. Bold indicates the highest unrounded accuracy or macro F1 within a dataset/model group, not statistical significance.
How routing concentrates errors Confidence distributions and error captureRouting analysis. On Reddit, routed posts have a 44.95% Phase 1 error rate compared with 3.08% over the full set (14.58 times higher). Confidence routing concentrates errors but leaves some errors in the accepted set.Additional evaluation: all three confusion matricesAdditional evaluation. Rows are reference labels and columns are final predictions. Each method is evaluated on the same 9,000 posts.
KEY FINDINGS
What the results establish
Selection concentrates errors.
On the main Reddit set, 1.82% of posts contain 26.49% of Phase 1 errors.
Output Stored response, parsing status, and final prediction for each routed post.
If a retained plan for g exists: load it and skip discovery.
Otherwise, give g task materials only; no post text or labels.
Have g SELECT relevant modules and ADAPT them to the task.
Have g IMPLEMENT the procedure; store it as the plan.
For each routed post, execute the plan on its original text without the Phase 1 label.
Request source quotes, three-label evidence, and a counterfactual check.
Parse the final label; retain Phase 1 if parsing fails.
Store the response, parsed status, and final prediction.
Selected operating point: T* = 1.480195; τ* = 0.70. The calibration risk constraint was non-binding within the prespecified grid. Source: manuscript Section V and the released notebooks.
04 / RECORDED CASES
From input to recorded outcome
Llama 3 SELF-DISCOVER on the synthetic Mixed Emotion set. Original inputs and unedited model responses from the final v6c run; no live inference.
MEV2_DEP_046Synthetic post · saved experiment record
Phase 1
Happy
68.82% calibrated confidence
Routing decision
Re-evaluate
68.82% < 70% threshold
Final prediction
Depression
Corrected against the reference target
Reference target: DepressionEvaluation only; not supplied to the model.
Input post
During recovering after a difficult week, I noticed a small success that I had been waiting for, and I kept track of dates, forms, and reminders. Even with those ordinary or positive moments, there was the thought that I was falling behind everyone else. I kept thinking about whether the moment was a turning point or just a pause, especially while making tea. By the end, the positive parts felt brief, and the heavier sadness was still the feeling I carried with me.
Full synthetic text, unchanged. Highlighting is editorial, not model attribution.
Evidence in the model response
Exact excerpts, not a reconstruction of internal reasoning.
The model identifies unresolved sadness despite the brief positive event. The full recorded response is available in the source records below.
No LLM response exists for this case. The router retained the Phase 1 label.
The plan is shared across posts; this response is generated for this input. Intermediate claims may be imperfect even when the final label is correct.
Full recorded model response Unedited output
The label changes from Happy to Depression. This is one of 28 corrections in the 300-example set; one new error gives 27 net corrections.
Examples were selected to show a correction, an introduced error, a parsing fallback, and an accepted error. They are not a representative sample. Records and selection provenance.
05 / SOURCE MATERIALS
Prompts and saved plans
Prompts are instructions; saved plans are model outputs. Direct asks for one label. CoT divides re-evaluation into five calls. SELF-DISCOVER first builds a reusable task-level plan, then applies it to each routed post.
Direct receives the post, shared classification policy, and Phase 1 label. It returns a final label without a rationale.
{policy} is the shared label policy; {text} is one post; {phase1_label} is the classifier's prediction.
You are an expert annotator for research-oriented, non-clinical emotion classification.

{policy}

Text:
{text}

The Phase 1 classifier predicted: {phase1_label}

Select the final label that best represents the text. Return no rationale and end with exactly one line in this form:
Final label: Depression
or Final label: Neutral
or Final label: Happy
The Reddit labels are community-derived proxies for Depression, Neutral, and Happy. The 300-example synthetic Mixed Emotion set tests mixed or shifting affect under a shared classification policy and informed Phase 2 prompt development.
Mixed Emotion was constructed using OpenAI GPT-5 via Codex and versioned scripts, with researcher-authored scenario and label constraints. Scenario-specific sentence templates produce recurring sentence frames; the examples should not be read as individually generated, unconstrained LLM samples. See the manuscript v3 construction clarification.
Two researchers uninvolved in data generation or Phase 2 prompt development independently annotated all 300 examples without seeing targets, scenario metadata, model outputs, or each other's responses. They agreed on 277 examples (92.33%; unweighted Cohen's κ = 0.8847). Agreement with the original targets was 96.00% and 96.33%. A third researcher checked completeness, record alignment, and statistics. No adjudication or post-audit relabeling was performed.
Subreddit-derived labels can carry topic and lexical biases. The annotation audit supports consistency with the shared policy, not clinical validity or generalization to real-world populations. The results do not establish a universal advantage of SELF-DISCOVER, the isolated contribution of its planning and evidence checks, or generalization to newer models and other platforms.
07 / REPRODUCIBILITY
Sources and verification
The public repository includes frozen configurations, exact prompts, saved plans, synthetic data, text-free predictions, aggregate reports, and verification scripts. Raw Reddit text, user identifiers, model weights, and the manuscript PDF are not redistributed here.
 Confidence-Guided